DATA ANNOTATION SERVICES

Data annotation for computer vision and AI.

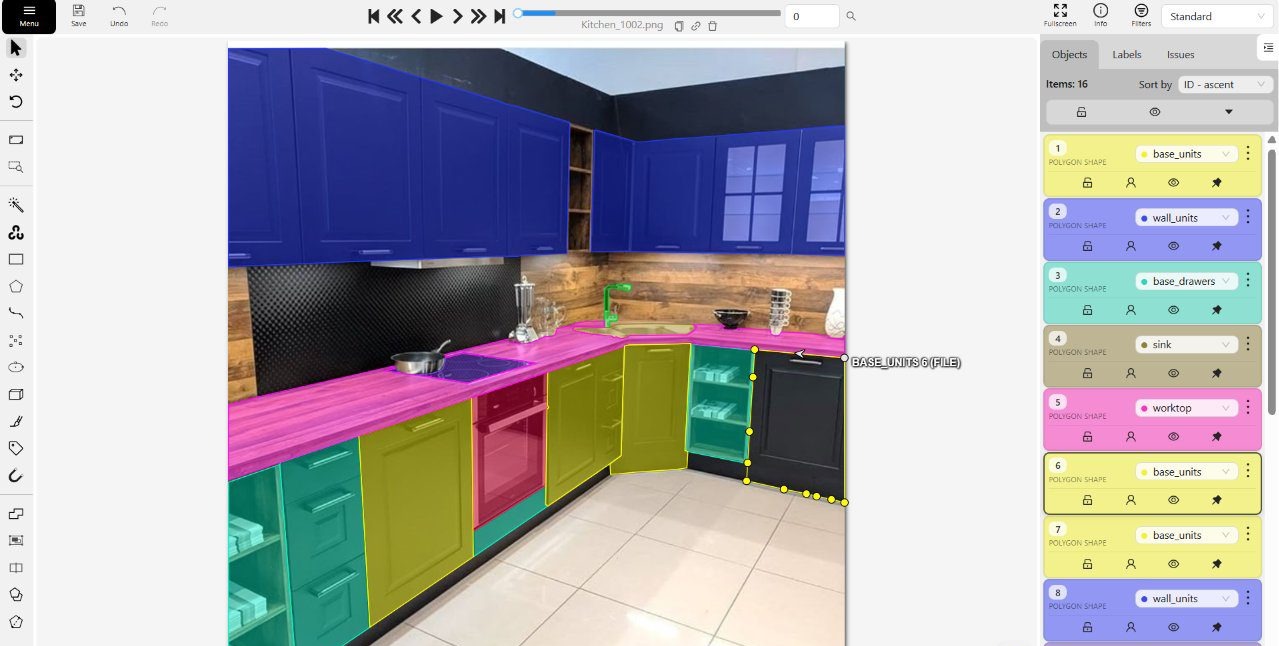
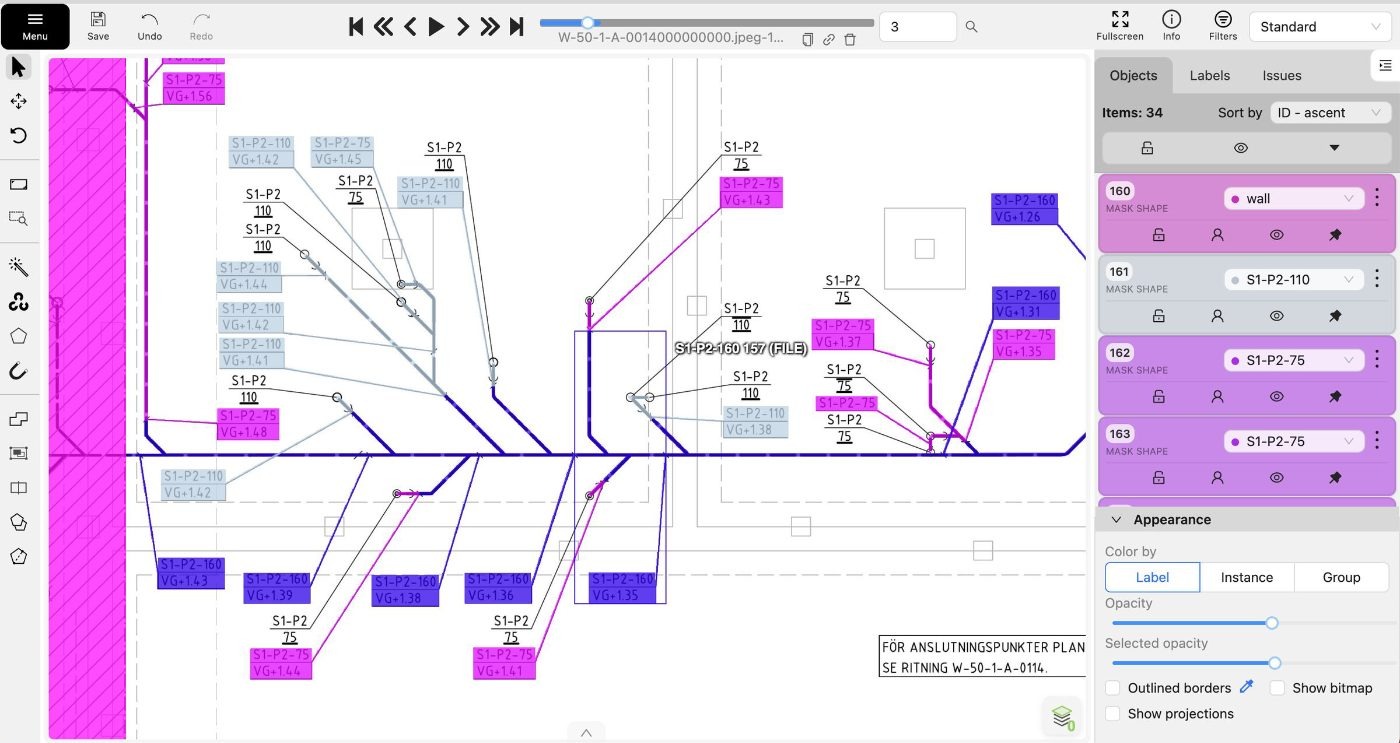
A managed team of trained annotators labelling your images and video to a written spec: bounding boxes, polygon segmentation, key points, classification and video annotation, checked before delivery.

400+
CV DATASETS
1M+
LABELLED IMAGES
200+
TRAINED ANNOTATORS
75
DOCUMENTED CASE STUDIES
ANNOTATION TYPES

What we label

Each type links to the projects in our portfolio that used it.

INDUSTRIES

Where we have done it

HOW WE WORK

A managed team, not a marketplace

Your data is labelled by people we train and manage, held to a written standard, and checked before it reaches you.

01
Spec

We agree the classes, edge cases and output format with you before labelling starts.

02
Label

Trained annotators work in CVAT, Labelbox or your own platform.

03
Review

Work is reviewed and scored per annotator, and errors are fed back as coaching.

04
Deliver

Labels arrive in your schema with a QA report, ready for training.

SELECTED WORK

Case studies
“Bilal and the team at WortelAI did a great job annotating images in a complex agricultural image dataset that we have. He and his team submitted accurate annotations and quickly responded to feedback throughout the engagement.”
Bo Meyering, Land Institute USA · More testimonials
FAQ

Common questions

Which annotation tools do you use?

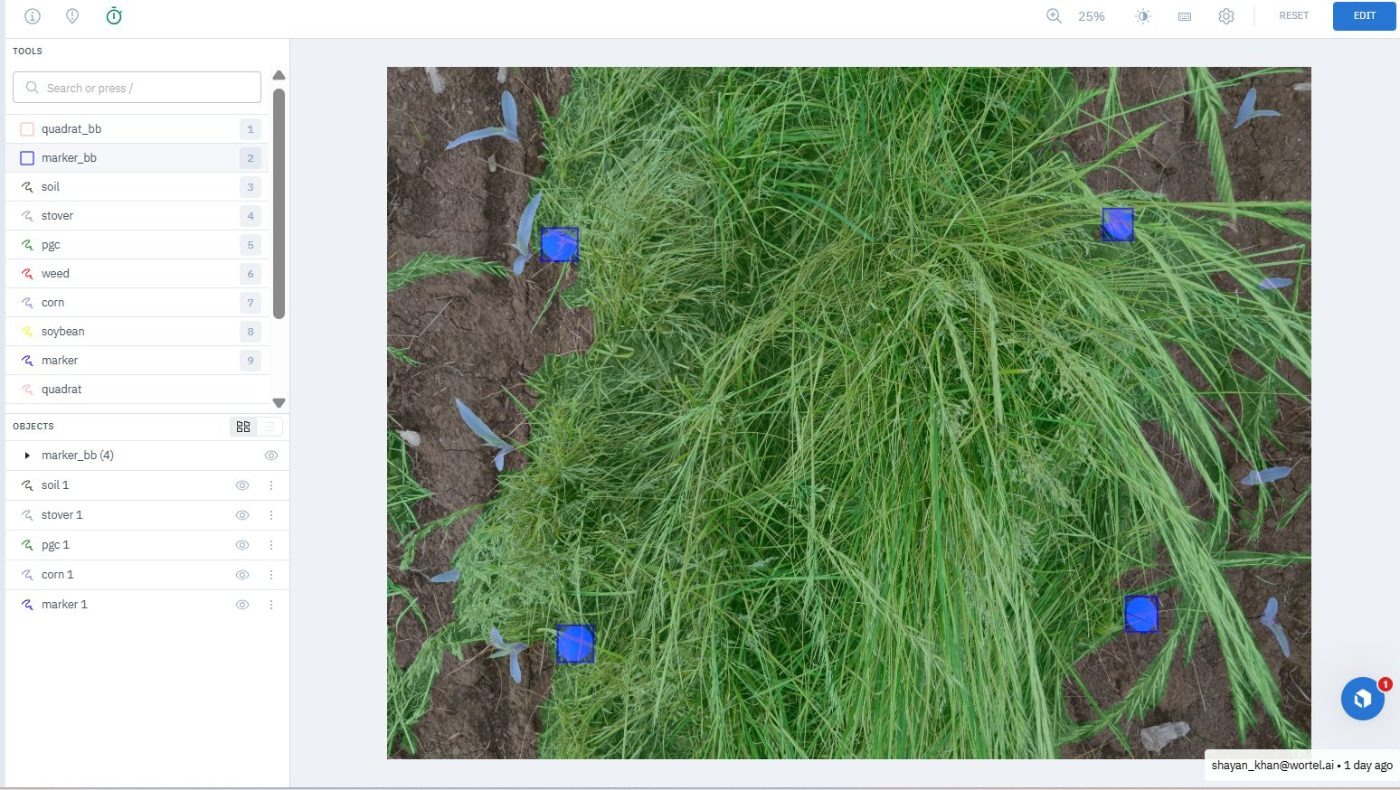
Most of our projects run in CVAT, and our cover-crop segmentation project was delivered in Labelbox. We can also work inside your own labelling platform and deliver in your schema.

Who does the annotation?

Our own managed team of 200+ trained annotators, not a crowd marketplace. Every project runs against a written spec, with per-annotator quality scoring and review before delivery.

What industries have you worked in?

Agriculture is our largest area, followed by real estate and interiors, construction drawings, waste management, transport and infrastructure, and wildlife and livestock. The portfolio lists every documented project.

Can you handle video as well as images?

Yes. Alongside image work, we run a large video program: 30,000+ hours of egocentric video segmented into atomic actions and described hand by hand.

How do we start?

Send a few hundred images or a couple of hours of video with your taxonomy. You get labelled data back, a QA report with the error taxonomy, and the questions we would ask before scaling.

Try us on your own data.

Send a few hundred images or a couple of hours of video with your taxonomy, and judge the labels yourself.

Start a pilot